Updated September 2026. Originally published July 2024.
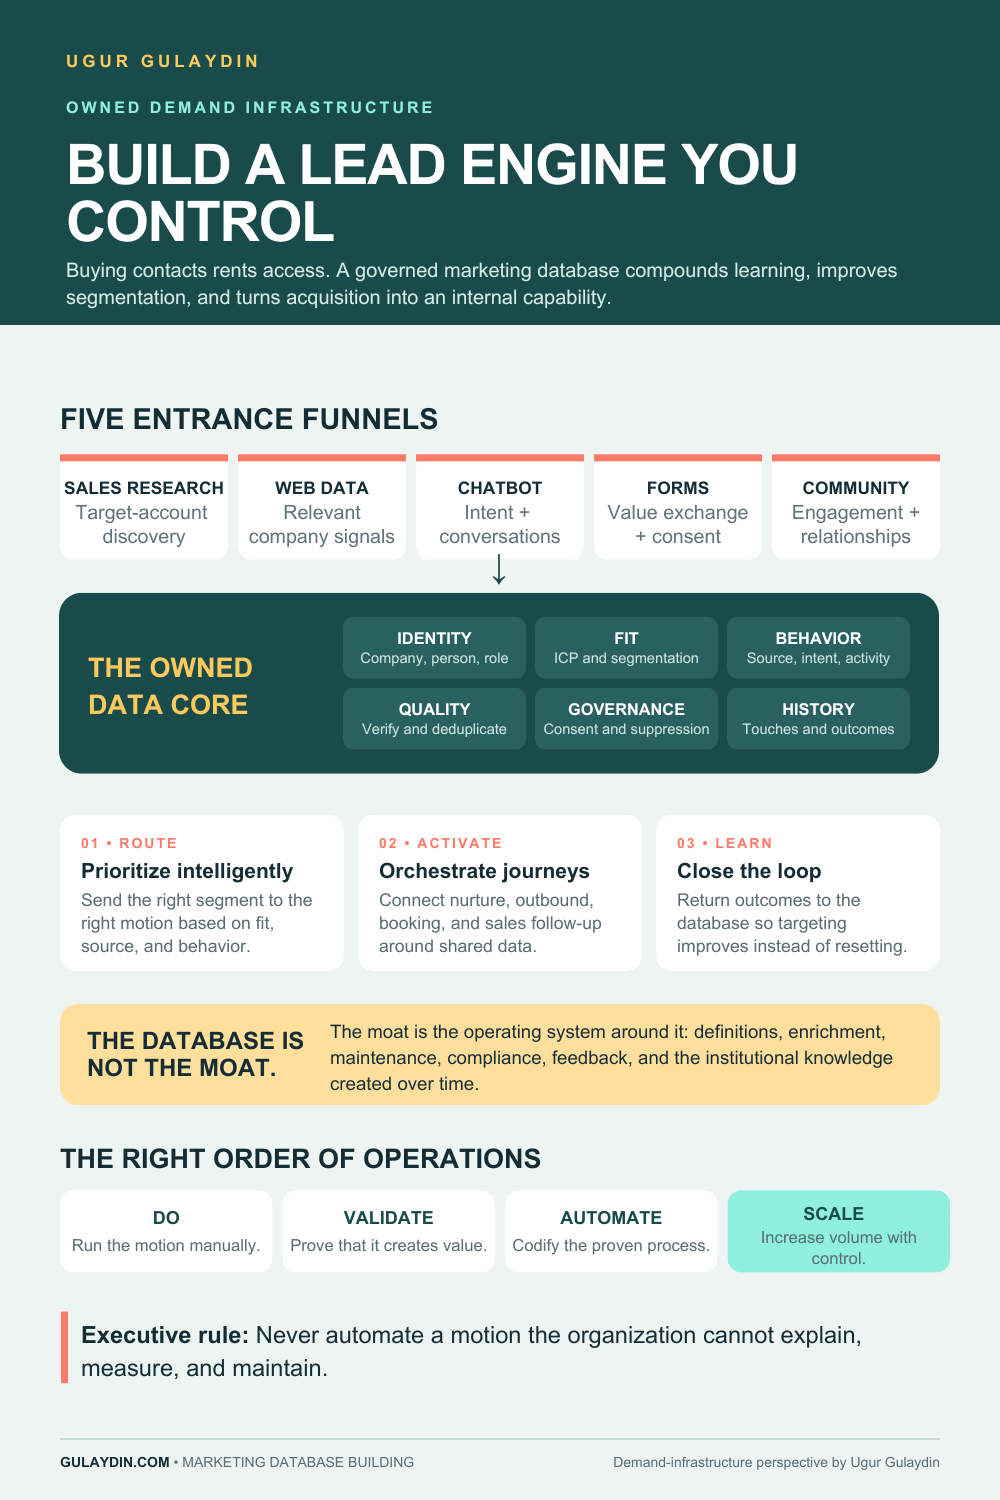
In 2024 I wrote that you should build your own marketing database instead of buying lists, and then described five ways to collect contacts.
The first half was right. The second half was a list of channels, and a list of channels is not a database.
What I run now is a system, and the difference is not scale. It is that the database stopped being a place where contacts are stored and became the thing that decides what happens next.
The inversion that matters
Almost everyone builds a target list by buying data, then filtering it.
We do the opposite. The list is built from our own database first, and purchased data is the fallback for net-new accounts we have no history with.
That ordering sounds like a small preference. It changes everything downstream.
Your own records know things no vendor can sell you. Who replied two years ago and said not yet. Which company already has three of your competitors’ tools. Who moved companies. Which accounts your delivery team quietly hates. Every one of those facts changes whether an account is worth a touch, and none of them exist in a purchased file.
Buying first means paying for a worse version of what you already own, then spending effort filtering it back down to what your own history would have told you for nothing.
The hub, and the part nobody budgets for
At the centre is a Postgres database of roughly thirty tables. Every step reads from it and writes back to it. Nothing is the source of truth except this.
The hard part is not the tables. It is the identity spine: the layer that resolves one human being, and one company, across four separate systems that all disagree about them.
A person exists in the CRM as one record, in the ticketing system as another, in the data warehouse as a third, and in the purchased enrichment file as a fourth. Different spellings, different email addresses, one of them out of date, two of them missing a job title. Until you decide which of those is the same person, every count you produce is wrong and every report is an argument.
Most teams underestimate this, build the pipeline first, and discover eighteen months later that their numbers cannot be reconciled. If you are going to do one thing from this article, do this one.
The sequence
Eleven steps, in five phases. Described by function, because the function is the transferable part.
Build the audience
- Source. Pull the target market from our own database first, then top up with purchased data only where we have no history.
- Clean and suppress. Deduplicate, apply exclusions, hard-suppress do-not-contact, and suppress the staff of every active client. That last one is not a legal requirement. It is how you avoid cold-emailing a customer’s IT director about a problem you are already being paid to solve.
- Verify. A verification waterfall so nothing is sent to an address that will bounce.
Enrich and qualify
- Enrich. Classify each company from its own website, then fill in names, titles, direct dials and profiles, and assemble a briefing for whoever will make the call.
- Grade. Score companies and contacts so reps work the best-fit accounts first rather than the top of an alphabetical list.
Send
- Render the copy. Personalised deterministically from a per-vertical configuration file.
- Human review. The built list goes to a spreadsheet and a person looks at it before anything leaves.
- Launch. Email and LinkedIn, with results syncing back to the hub.
Respond
- Work the replies. Agents read every reply, discard out-of-office and junk, route the warm ones to a human, identify which company a website visitor belongs to, and handle inbound form fills.
Route and learn
- Sync. Reconcile contacts, sends and outcomes between the CRM and the hub so activity and reporting agree.
- Measure. Score intent, and recompute which messaging angles are actually converting.
No language model writes the email
This is the decision I would defend hardest, and it runs against almost everything being sold right now.
Outbound copy is rendered deterministically from a configuration file for that vertical. The same inputs produce the same message every time. There is no model generating text at send time.
The reason is simple. A message going to a stranger who has never heard of you is the worst possible place to accept a small probability of an invented fact. Not because the writing would be poor. Because it would occasionally be confidently wrong about their company, and you only get one of those before that account is closed permanently.
That does not mean AI is absent. It does a great deal of work, all of it upstream:
- Classifying what a company actually does, from its own website
- Grading fit, so the list is ordered by something other than guesswork
- Reading and triaging every reply that comes back
- Recomputing which angles are working
The distinction is between using a model to decide and using it to speak. Deciding is reversible and checkable. Speaking to a stranger on your behalf is neither.
This is the same instinct I described in AI content and E-E-A-T. The machine does the sourcing, the classification and the admin. The words that reach a human being are ones a human being approved.
Signals jump the queue
Running alongside all of this is a signals engine that watches public sources for events that change whether an account should be contacted today rather than next quarter.
The categories worth watching in our market:
- Published vulnerability catalogues, which tell you what a company with a given stack is currently exposed to
- Public breach and incident disclosures, which tell you who has just had the worst week of their year
- Regulatory filings and rule changes, which create deadlines that were not there last month
- Hiring activity, which is the most honest statement a company makes about its priorities
When a signal matches an account in the database, a prioritised brief goes to the right person in chat, and that account moves to the front of the queue.
The point is not the alerting. It is that relevance stops being a property of your copy and becomes a property of your timing. The best written email in the world, sent in a quarter when nothing is happening, loses to a plain one sent the week a deadline appeared.
What this costs to build
I am not going to pretend this assembled itself.
Roughly 87 scripts, which doubled in about four months. Four agents running on a scheduler. Around thirty tables. Eleven platforms connected. Most of it is not clever, in the same way that most of conversion testing is not clever: it is reconciliation, backfilling, and handling the cases where two systems disagree.
If you are considering this, the honest sequence is:
- Identity spine first. Before any automation. If you cannot say with confidence that these two records are the same person, nothing built on top will survive contact with a real dataset.
- Suppression and verification next. These protect the asset you are building. Deliverability damage takes months to repair and is invisible until it is severe.
- Then enrichment and grading, because ordering the list is worth more than extending it.
- Automation last. Automating a process you have not yet got right just produces mistakes faster, which is the lesson I keep relearning in every workflow I have documented.
What the 2024 version left out
The five channels in the original version of this article were not wrong. Sales navigator searches, chatbots, forms and communities all still put contacts into a database.
They were just the least important part, and I gave them the whole article.
The value was never in the collection. It is in the resolution, the suppression, the grading and the timing. A contact you cannot match to your own history, cannot verify, and cannot rank is not an asset. It is a row.
Which is why the measure that matters is not how many contacts you have. It is the one I use for everything else now: what does one appointment cost, and what is one worth.
This article was substantially rewritten in September 2026. The original July 2024 version described five manual channels for collecting contacts, including scraping approaches that no longer work as written and that I would no longer recommend without the suppression and verification steps described above. The sections on the identity spine, deterministic copy rendering, the signals engine and the build sequence are new. Vendor names and implementation details are deliberately omitted.